

Free 365 Days Exam Updates ACD-301 dumps with test Engine Practice
Updated Verified ACD-301 dumps Q&As - 100% Pass Guaranteed
NEW QUESTION # 18
You are in a backlog refinement meeting with the development team and the product owner. You review a story for an integration involving a third-party system. A payload will be sent from the Appian system through the integration to the third-party system. The story is 21 points on a Fibonacci scale and requires development from your Appian team as well as technical resources from the third-party system. This item is crucial to your project's success. What are the two recommended steps to ensure this story can be developed effectively?
- A. Acquire testing steps from QA resources.
- B. Break down the item into smaller stories.
- C. Maintain a communication schedule with the third-party resources.
- D. Identify subject matter experts (SMEs) to perform user acceptance testing (UAT).
Answer: B,C
Explanation:
Comprehensive and Detailed In-Depth Explanation:
This question involves a complex integration story rated at 21 points on the Fibonacci scale, indicating significant complexity and effort. Appian Lead Developer best practices emphasize effective collaboration, risk mitigation, and manageable development scopes for such scenarios. The two most critical steps are:
Option C (Maintain a communication schedule with the third-party resources):
Integrations with third-party systems require close coordination, as Appian developers depend on external teams for endpoint specifications, payload formats, authentication details, and testing support. Establishing a regular communication schedule ensures alignment on requirements, timelines, and issue resolution. Appian's Integration Best Practices documentation highlights the importance of proactive communication with external stakeholders to prevent delays and misunderstandings, especially for critical project components.
Option D (Break down the item into smaller stories):
A 21-point story is considered large by Agile standards (Fibonacci scale typically flags anything above 13 as complex). Appian's Agile Development Guide recommends decomposing large stories into smaller, independently deliverable pieces to reduce risk, improve testability, and enable iterative progress. For example, the integration could be split into tasks like designing the payload structure, building the integration object, and testing the connection-each manageable within a sprint. This approach aligns with the principle of delivering value incrementally while maintaining quality.
Option A (Acquire testing steps from QA resources): While QA involvement is valuable, this step is more relevant during the testing phase rather than backlog refinement or development preparation. It's not a primary step for ensuring effective development of the story.
Option B (Identify SMEs for UAT): User acceptance testing occurs after development, during the validation phase. Identifying SMEs is important but not a key step in ensuring the story is developed effectively during the refinement and coding stages.
By choosing C and D, you address both the external dependency (third-party coordination) and internal complexity (story size), ensuring a smoother development process for this critical integration.
NEW QUESTION # 19
You need to generate a PDF document with specific formatting. Which approach would you recommend?
- A. Create an embedded interface with the necessary content and ask the user to use the browser "Print" functionality to save it as a PDF.
- B. There is no way to fulfill the requirement using Appian. Suggest sending the content as a plain email instead.
- C. Use the Word Doc from Template smart service in a process model to add the specific format.
- D. Use the PDF from XSL-FO Transformation smart service to generate the content with the specific format.
Answer: D
Explanation:
Comprehensive and Detailed In-Depth Explanation:
As an Appian Lead Developer, generating a PDF with specific formatting is a common requirement, and Appian provides several tools to achieve this. The question emphasizes "specific formatting," which implies precise control over layout, styling, and content structure. Let's evaluate each option based on Appian's official documentation and capabilities:
A . Create an embedded interface with the necessary content and ask the user to use the browser "Print" functionality to save it as a PDF:
This approach involves designing an interface (e.g., using SAIL components) and relying on the browser's native print-to-PDF feature. While this is feasible for simple content, it lacks precision for "specific formatting." Browser rendering varies across devices and browsers, and print styles (e.g., CSS) are limited in Appian's control. Appian Lead Developer best practices discourage relying on client-side functionality for critical document generation due to inconsistency and lack of automation. This is not a recommended solution for a production-grade requirement.
B . Use the PDF from XSL-FO Transformation smart service to generate the content with the specific format:
This is the correct choice. The "PDF from XSL-FO Transformation" smart service (available in Appian's process modeling toolkit) allows developers to generate PDFs programmatically with precise formatting using XSL-FO (Extensible Stylesheet Language Formatting Objects). XSL-FO provides fine-grained control over layout, fonts, margins, and styling-ideal for "specific formatting" requirements. In a process model, you can pass XML data and an XSL-FO stylesheet to this smart service, producing a downloadable PDF. Appian's documentation highlights this as the preferred method for complex PDF generation, making it a robust, scalable, and Appian-native solution.
C . Use the Word Doc from Template smart service in a process model to add the specific format:
This option uses the "Word Doc from Template" smart service to generate a Microsoft Word document from a template (e.g., a .docx file with placeholders). While it supports formatting defined in the template and can be converted to PDF post-generation (e.g., via a manual step or external tool), it's not a direct PDF solution. Appian doesn't natively convert Word to PDF within the platform, requiring additional steps outside the process model. For "specific formatting" in a PDF, this is less efficient and less precise than the XSL-FO approach, as Word templates are better suited for editable documents rather than final PDFs.
D . There is no way to fulfill the requirement using Appian. Suggest sending the content as a plain email instead:
This is incorrect. Appian provides multiple tools for document generation, including PDFs, as evidenced by options B and C. Suggesting a plain email fails to meet the requirement of generating a formatted PDF and contradicts Appian's capabilities. Appian Lead Developer training emphasizes leveraging platform features to meet business needs, ruling out this option entirely.
Conclusion: The PDF from XSL-FO Transformation smart service (B) is the recommended approach. It provides direct PDF generation with specific formatting control within Appian's process model, aligning with best practices for document automation and precision. This method is scalable, repeatable, and fully supported by Appian's architecture.
Appian Documentation: "PDF from XSL-FO Transformation Smart Service" (Process Modeling > Smart Services).
Appian Lead Developer Certification: Document Generation Module (PDF Generation Techniques).
Appian Best Practices: "Generating Documents in Appian" (XSL-FO vs. Template-Based Approaches).
NEW QUESTION # 20
You are the lead developer for an Appian project, in a backlog refinement meeting. You are presented with the following user story:
"As a restaurant customer, I need to be able to place my food order online to avoid waiting in line for takeout." Which two functional acceptance criteria would you consider 'good'?
- A. The user will receive an email notification when their order is completed.
- B. The user cannot submit the form without filling out all required fields.
- C. The user will click Save, and the order information will be saved in the ORDER table and have audit history.
- D. The system must handle up to 500 unique orders per day.
Answer: B,C
Explanation:
Comprehensive and Detailed In-Depth Explanation:
As an Appian Lead Developer, defining "good" functional acceptance criteria for a user story requires ensuring they are specific, testable, and directly tied to the user's need (placing an online food order to avoid waiting in line). Good criteria focus on functionality, usability, and reliability, aligning with Appian's Agile and design best practices. Let's evaluate each option:
A . The user will click Save, and the order information will be saved in the ORDER table and have audit history:
This is a "good" criterion. It directly validates the core functionality of the user story-placing an order online. Saving order data in the ORDER table (likely via a process model or Data Store Entity) ensures persistence, and audit history (e.g., using Appian's audit logs or database triggers) tracks changes, supporting traceability and compliance. This is specific, testable (e.g., verify data in the table and logs), and essential for the user's goal, aligning with Appian's data management and user experience guidelines.
B . The user will receive an email notification when their order is completed:
While useful, this is a "nice-to-have" enhancement, not a core requirement of the user story. The story focuses on placing an order online to avoid waiting, not on completion notifications. Email notifications add value but aren't essential for validating the primary functionality. Appian's user story best practices prioritize criteria tied to the main user need, making this secondary and not "good" in this context.
C . The system must handle up to 500 unique orders per day:
This is a non-functional requirement (performance/scalability), not a functional acceptance criterion. It describes system capacity, not specific user behavior or functionality. While important for design, it's not directly testable for the user story's outcome (placing an order) and isn't tied to the user's experience. Appian's Agile methodologies separate functional and non-functional requirements, making this less relevant as a "good" criterion here.
D . The user cannot submit the form without filling out all required fields:
This is a "good" criterion. It ensures data integrity and usability by preventing incomplete orders, directly supporting the user's ability to place a valid online order. In Appian, this can be implemented using form validation (e.g., required attributes in SAIL interfaces or process model validations), making it specific, testable (e.g., verify form submission fails with missing fields), and critical for a reliable user experience. This aligns with Appian's UI design and user story validation standards.
Conclusion: The two "good" functional acceptance criteria are A (order saved with audit history) and D (required fields enforced). These directly validate the user story's functionality (placing a valid order online), are testable, and ensure a reliable, user-friendly experience-aligning with Appian's Agile and design best practices for user stories.
Appian Documentation: "Writing Effective User Stories and Acceptance Criteria" (Functional Requirements).
Appian Lead Developer Certification: Agile Development Module (Acceptance Criteria Best Practices).
Appian Best Practices: "Designing User Interfaces in Appian" (Form Validation and Data Persistence).
NEW QUESTION # 21
You add an index on the searched field of a MySQL table with many rows (>100k). The field would benefit greatly from the index in which three scenarios?
- A. The field contains a textual short business code.
- B. The field contains big integers, above and below 0.
- C. The field contains many datetimes, covering a large range.
- D. The field contains a structured JSON.
- E. The field contains long unstructured text such as a hash.
Answer: A,B,C
Explanation:
Comprehensive and Detailed In-Depth Explanation:
Adding an index to a searched field in a MySQL table with over 100,000 rows improves query performance by reducing the number of rows scanned during searches, joins, or filters. The benefit of an index depends on the field's data type, cardinality (uniqueness), and query patterns. MySQL indexing best practices, as aligned with Appian's Database Optimization Guidelines, highlight scenarios where indices are most effective.
Option A (The field contains a textual short business code):
This benefits greatly from an index. A short business code (e.g., a 5-10 character identifier like "CUST123") typically has high cardinality (many unique values) and is often used in WHERE clauses or joins. An index on this field speeds up exact-match queries (e.g., WHERE business_code = 'CUST123'), which are common in Appian applications for lookups or filtering.
Option C (The field contains many datetimes, covering a large range):
This is highly beneficial. Datetime fields with a wide range (e.g., transaction timestamps over years) are frequently queried with range conditions (e.g., WHERE datetime BETWEEN '2024-01-01' AND '2025-01-01') or sorting (e.g., ORDER BY datetime). An index on this field optimizes these operations, especially in large tables, aligning with Appian's recommendation to index time-based fields for performance.
Option D (The field contains big integers, above and below 0):
This benefits significantly. Big integers (e.g., IDs or quantities) with a broad range and high cardinality are ideal for indexing. Queries like WHERE id > 1000 or WHERE quantity < 0 leverage the index for efficient range scans or equality checks, a common pattern in Appian data store queries.
Option B (The field contains long unstructured text such as a hash):
This benefits less. Long unstructured text (e.g., a 128-character SHA hash) has high cardinality but is less efficient for indexing due to its size. MySQL indices on large text fields can slow down writes and consume significant storage, and full-text searches are better handled with specialized indices (e.g., FULLTEXT), not standard B-tree indices. Appian advises caution with indexing large text fields unless necessary.
Option E (The field contains a structured JSON):
This is minimally beneficial with a standard index. MySQL supports JSON fields, but a regular index on the entire JSON column is inefficient for large datasets (>100k rows) due to its variable structure. Generated columns or specialized JSON indices (e.g., using JSON_EXTRACT) are required for targeted queries (e.g., WHERE JSON_EXTRACT(json_col, '$.key') = 'value'), but this requires additional setup beyond a simple index, reducing its immediate benefit.
For a table with over 100,000 rows, indices are most effective on fields with high selectivity and frequent query usage (e.g., short codes, datetimes, integers), making A, C, and D the optimal scenarios.
NEW QUESTION # 22
You are the project lead for an Appian project with a supportive product owner and complex business requirements involving a customer management system. Each week, you notice the product owner becoming more irritated and not devoting as much time to the project, resulting in tickets becoming delayed due to a lack of involvement. Which two types of meetings should you schedule to address this issue?
- A. An additional daily stand-up meeting to ensure you have more of the product owner's time.
- B. A risk management meeting with your program manager to escalate the delayed tickets.
- C. A meeting with the sponsor to discuss the product owner's performance and request a replacement.
- D. A sprint retrospective with the product owner and development team to discuss team performance.
Answer: B,D
Explanation:
Comprehensive and Detailed In-Depth Explanation:
As an Appian Lead Developer, managing stakeholder engagement and ensuring smooth project progress are critical responsibilities. The scenario describes a product owner whose decreasing involvement is causing delays, which requires a proactive and collaborative approach rather than an immediate escalation to replacement. Let's analyze each option:
A . An additional daily stand-up meeting: While daily stand-ups are a core Agile practice to align the team, adding another one specifically to secure the product owner's time is inefficient. Appian's Agile methodology (aligned with Scrum) emphasizes that stand-ups are for the development team to coordinate, not to force stakeholder availability. The product owner's irritation might increase with additional meetings, making this less effective.
B . A risk management meeting with your program manager: This is a correct choice. Appian Lead Developer documentation highlights the importance of risk management in complex projects (e.g., customer management systems). Delays due to lack of product owner involvement constitute a project risk. Escalating this to the program manager ensures visibility and allows for strategic mitigation, such as resource reallocation or additional support, without directly confronting the product owner in a way that could damage the relationship. This aligns with Appian's project governance best practices.
C . A sprint retrospective with the product owner and development team: This is also a correct choice. The sprint retrospective, as per Appian's Agile guidelines, is a key ceremony to reflect on what's working and what isn't. Including the product owner fosters collaboration and provides a safe space to address their reduced involvement and its impact on ticket delays. It encourages team accountability and aligns with Appian's focus on continuous improvement in Agile development.
D . A meeting with the sponsor to discuss the product owner's performance and request a replacement: This is premature and not recommended as a first step. Appian's Lead Developer training emphasizes maintaining strong stakeholder relationships and resolving issues collaboratively before escalating to drastic measures like replacement. This option risks alienating the product owner and disrupting the project further, which contradicts Appian's stakeholder management principles.
Conclusion: The best approach combines B (risk management meeting) to address the immediate risk of delays with a higher-level escalation and C (sprint retrospective) to collaboratively resolve the product owner's engagement issues. These align with Appian's Agile and leadership strategies for Lead Developers.
Appian Lead Developer Certification: Agile Project Management Module (Risk Management and Stakeholder Engagement).
Appian Documentation: "Best Practices for Agile Development in Appian" (Sprint Retrospectives and Team Collaboration).
NEW QUESTION # 23
You have created a Web API in Appian with the following URL to call it: https://exampleappiancloud.com/suite/webapi/user_management/users?username=john.smith. Which is the correct syntax for referring to the username parameter?
- A. httpRequest.queryParameters.users.username
- B. httpRequest.queryParameters.username
- C. httpRequest.formData.username
- D. httpRequest.users.username
Answer: B
Explanation:
Comprehensive and Detailed In-Depth Explanation:
In Appian, when creating a Web API, parameters passed in the URL (e.g., query parameters) are accessed within the Web API expression using the httpRequest object. The URL https://exampleappiancloud.com/suite/webapi/user_management/users?username=john.smith includes a query parameter username with the value john.smith. Appian's Web API documentation specifies how to handle such parameters in the expression rule associated with the Web API.
Option D (httpRequest.queryParameters.username):
This is the correct syntax. The httpRequest.queryParameters object contains all query parameters from the URL. Since username is a single query parameter, you access it directly as httpRequest.queryParameters.username. This returns the value john.smith as a text string, which can then be used in the Web API logic (e.g., to query a user record). Appian's expression language treats query parameters as key-value pairs under queryParameters, making this the standard approach.
Option A (httpRequest.queryParameters.users.username):
This is incorrect. The users part suggests a nested structure (e.g., users as a parameter containing a username subfield), which does not match the URL. The URL only defines username as a top-level query parameter, not a nested object.
Option B (httpRequest.users.username):
This is invalid. The httpRequest object does not have a direct users property. Query parameters are accessed via queryParameters, and there's no indication of a users object in the URL or Appian's Web API model.
Option C (httpRequest.formData.username):
This is incorrect. The httpRequest.formData object is used for parameters passed in the body of a POST or PUT request (e.g., form submissions), not for query parameters in a GET request URL. Since the username is part of the query string (?username=john.smith), formData does not apply.
The correct syntax leverages Appian's standard handling of query parameters, ensuring the Web API can process the username value effectively.
NEW QUESTION # 24
You are planning a strategy around data volume testing for an Appian application that queries and writes to a MySQL database. You have administrator access to the Appian application and to the database. What are two key considerations when designing a data volume testing strategy?
- A. Data model changes must wait until towards the end of the project.
- B. Data from previous tests needs to remain in the testing environment prior to loading prepopulated data.
- C. Testing with the correct amount of data should be in the definition of done as part of each sprint.
- D. Large datasets must be loaded via Appian processes.
- E. The amount of data that needs to be populated should be determined by the project sponsor and the stakeholders based on their estimation.
Answer: C,E
Explanation:
Comprehensive and Detailed In-Depth Explanation:
Data volume testing ensures an Appian application performs efficiently under realistic data loads, especially when interacting with external databases like MySQL. As an Appian Lead Developer with administrative access, the focus is on scalability, performance, and iterative validation. The two key considerations are:
Option C (The amount of data that needs to be populated should be determined by the project sponsor and the stakeholders based on their estimation):
Determining the appropriate data volume is critical to simulate real-world usage. Appian's Performance Testing Best Practices recommend collaborating with stakeholders (e.g., project sponsors, business analysts) to define expected data sizes based on production scenarios. This ensures the test reflects actual requirements-like peak transaction volumes or record counts-rather than arbitrary guesses. For example, if the application will handle 1 million records in production, stakeholders must specify this to guide test data preparation.
Option D (Testing with the correct amount of data should be in the definition of done as part of each sprint):
Appian's Agile Development Guide emphasizes incorporating performance testing (including data volume) into the Definition of Done (DoD) for each sprint. This ensures that features are validated under realistic conditions iteratively, preventing late-stage performance issues. With admin access, you can query/write to MySQL and assess query performance or write latency with the specified data volume, aligning with Appian's recommendation to "test early and often." Option A (Data from previous tests needs to remain in the testing environment prior to loading prepopulated data): This is impractical and risky. Retaining old test data can skew results, introduce inconsistencies, or violate data integrity (e.g., duplicate keys in MySQL). Best practices advocate for a clean, controlled environment with fresh, prepopulated data per test cycle.
Option B (Large datasets must be loaded via Appian processes): While Appian processes can load data, this is not a requirement. With database admin access, you can use SQL scripts or tools like MySQL Workbench for faster, more efficient data population, bypassing Appian process overhead. Appian documentation notes this as a preferred method for large datasets.
Option E (Data model changes must wait until towards the end of the project): Delaying data model changes contradicts Agile principles and Appian's iterative design approach. Changes should occur as needed throughout development to adapt to testing insights, not be deferred.
NEW QUESTION # 25
You need to connect Appian with LinkedIn to retrieve personal information about the users in your application. This information is considered private, and users should allow Appian to retrieve their information. Which authentication method would you recommend to fulfill this request?
- A. Basic Authentication with dedicated account's login information
- B. API Key Authentication
- C. OAuth 2.0: Authorization Code Grant
- D. Basic Authentication with user's login information
Answer: C
Explanation:
Comprehensive and Detailed In-Depth Explanation:
As an Appian Lead Developer, integrating with an external system like LinkedIn to retrieve private user information requires a secure, user-consented authentication method that aligns with Appian's capabilities and industry standards. The requirement specifies that users must explicitly allow Appian to access their private data, which rules out methods that don't involve user authorization. Let's evaluate each option based on Appian's official documentation and LinkedIn's API requirements:
A . API Key Authentication:
API Key Authentication involves using a single static key to authenticate requests. While Appian supports this method via Connected Systems (e.g., HTTP Connected System with an API key header), it's unsuitable here. API keys authenticate the application, not the user, and don't provide a mechanism for individual user consent. LinkedIn's API for private data (e.g., profile information) requires per-user authorization, which API keys cannot facilitate. Appian documentation notes that API keys are best for server-to-server communication without user context, making this option inadequate for the requirement.
B . Basic Authentication with user's login information:
This method uses a username and password (typically base64-encoded) provided by each user. In Appian, Basic Authentication is supported in Connected Systems, but applying it here would require users to input their LinkedIn credentials directly into Appian. This is insecure, impractical, and against LinkedIn's security policies, as it exposes user passwords to the application. Appian Lead Developer best practices discourage storing or handling user credentials directly due to security risks (e.g., credential leakage) and maintenance challenges. Moreover, LinkedIn's API doesn't support Basic Authentication for user-specific data access-it requires OAuth 2.0. This option is not viable.
C . Basic Authentication with dedicated account's login information:
This involves using a single, dedicated LinkedIn account's credentials to authenticate all requests. While technically feasible in Appian's Connected System (using Basic Authentication), it fails to meet the requirement that "users should allow Appian to retrieve their information." A dedicated account would access data on behalf of all users without their individual consent, violating privacy principles and LinkedIn's API terms. LinkedIn restricts such approaches, requiring user-specific authorization for private data. Appian documentation advises against blanket credentials for user-specific integrations, making this option inappropriate.
D . OAuth 2.0: Authorization Code Grant:
This is the recommended choice. OAuth 2.0 Authorization Code Grant, supported natively in Appian's Connected System framework, is designed for scenarios where users must authorize an application (Appian) to access their private data on a third-party service (LinkedIn). In this flow, Appian redirects users to LinkedIn's authorization page, where they grant permission. Upon approval, LinkedIn returns an authorization code, which Appian exchanges for an access token via the Token Request Endpoint. This token enables Appian to retrieve private user data (e.g., profile details) securely and per user. Appian's documentation explicitly recommends this method for integrations requiring user consent, such as LinkedIn, and provides tools like a!authorizationLink() to handle authorization failures gracefully. LinkedIn's API (e.g., v2 API) mandates OAuth 2.0 for personal data access, aligning perfectly with this approach.
Conclusion: OAuth 2.0: Authorization Code Grant (D) is the best method. It ensures user consent, complies with LinkedIn's API requirements, and leverages Appian's secure integration capabilities. In practice, you'd configure a Connected System in Appian with LinkedIn's Client ID, Client Secret, Authorization Endpoint (e.g., https://www.linkedin.com/oauth/v2/authorization), and Token Request Endpoint (e.g., https://www.linkedin.com/oauth/v2/accessToken), then use an Integration object to call LinkedIn APIs with the access token. This solution is scalable, secure, and aligns with Appian Lead Developer certification standards for third-party integrations.
Appian Documentation: "Setting Up a Connected System with the OAuth 2.0 Authorization Code Grant" (Connected Systems).
Appian Lead Developer Certification: Integration Module (OAuth 2.0 Configuration and Best Practices).
LinkedIn Developer Documentation: "OAuth 2.0 Authorization Code Flow" (API Authentication Requirements).
NEW QUESTION # 26
You are tasked to build a large-scale acquisition application for a prominent customer. The acquisition process tracks the time it takes to fulfill a purchase request with an award.
The customer has structured the contract so that there are multiple application development teams.
How should you design for multiple processes and forms, while minimizing repeated code?
- A. Create a Scrum of Scrums sprint meeting for the team leads.
- B. Create duplicate processes and forms as needed.
- C. Create a common objects application.
- D. Create a Center of Excellence (CoE).
Answer: C
Explanation:
Comprehensive and Detailed In-Depth Explanation:
As an Appian Lead Developer, designing a large-scale acquisition application with multiple development teams requires a strategy to manage processes, forms, and code reuse effectively. The goal is to minimize repeated code (e.g., duplicate interfaces, process models) while ensuring scalability and maintainability across teams. Let's evaluate each option:
A . Create a Center of Excellence (CoE):
A Center of Excellence is an organizational structure or team focused on standardizing practices, training, and governance across projects. While beneficial for long-term consistency, it doesn't directly address the technical design of minimizing repeated code for processes and forms. It's a strategic initiative, not a design solution, and doesn't solve the immediate need for code reuse. Appian's documentation mentions CoEs for governance but not as a primary design approach, making this less relevant here.
B . Create a common objects application:
This is the best recommendation. In Appian, a "common objects application" (or shared application) is used to store reusable components like expression rules, interfaces, process models, constants, and data types (e.g., CDTs). For a large-scale acquisition application with multiple teams, centralizing shared objects (e.g., rule!CommonForm, pm!CommonProcess) ensures consistency, reduces duplication, and simplifies maintenance. Teams can reference these objects in their applications, adhering to Appian's design best practices for scalability. This approach minimizes repeated code while allowing team-specific customizations, aligning with Lead Developer standards for large projects.
C . Create a Scrum of Scrums sprint meeting for the team leads:
A Scrum of Scrums meeting is a coordination mechanism for Agile teams, focusing on aligning sprint goals and resolving cross-team dependencies. While useful for collaboration, it doesn't address the technical design of minimizing repeated code-it's a process, not a solution for code reuse. Appian's Agile methodologies support such meetings, but they don't directly reduce duplication in processes and forms, making this less applicable.
D . Create duplicate processes and forms as needed:
Duplicating processes and forms (e.g., copying interface!PurchaseForm for each team) leads to redundancy, increased maintenance effort, and potential inconsistencies (e.g., divergent logic). This contradicts the goal of minimizing repeated code and violates Appian's design principles for reusability and efficiency. Appian's documentation strongly discourages duplication, favoring shared objects instead, making this the least effective option.
Conclusion: Creating a common objects application (B) is the recommended design. It centralizes reusable processes, forms, and other components, minimizing code duplication across teams while ensuring consistency and scalability for the large-scale acquisition application. This leverages Appian's application architecture for shared resources, aligning with Lead Developer best practices for multi-team projects.
Appian Documentation: "Designing Large-Scale Applications" (Common Application for Reusable Objects).
Appian Lead Developer Certification: Application Design Module (Minimizing Code Duplication).
Appian Best Practices: "Managing Multi-Team Development" (Shared Objects Strategy).
To build a large scale acquisition application for a prominent customer, you should design for multiple processes and forms, while minimizing repeated code. One way to do this is to create a common objects application, which is a shared application that contains reusable components, such as rules, constants, interfaces, integrations, or data types, that can be used by multiple applications. This way, you can avoid duplication and inconsistency of code, and make it easier to maintain and update your applications. You can also use the common objects application to define common standards and best practices for your application development teams, such as naming conventions, coding styles, or documentation guidelines. Verified [Appian Best Practices], [Appian Design Guidance]
NEW QUESTION # 27
You are on a call with a new client, and their program lead is concerned about how their legacy systems will integrate with Appian. The lead wants to know what authentication methods are supported by Appian. Which three authentication methods are supported?
- A. SAML
- B. API Keys
- C. Biometrics
- D. Active Directory
- E. OAuth
- F. CAC
Answer: A,D,E
Explanation:
Comprehensive and Detailed In-Depth Explanation:
As an Appian Lead Developer, addressing a client's concerns about integrating legacy systems with Appian requires accurately identifying supported authentication methods for system-to-system communication or user access. The question focuses on Appian's integration capabilities, likely for both user authentication (e.g., SSO) and API authentication, as legacy system integration often involves both. Appian's documentation outlines supported methods in its Connected Systems and security configurations. Let's evaluate each option:
A . API Keys:
API Key authentication involves a static key sent in requests (e.g., via headers). Appian supports this for outbound integrations in Connected Systems (e.g., HTTP Authentication with an API key), allowing legacy systems to authenticate Appian calls. However, it's not a user authentication method for Appian's platform login-it's for system-to-system integration. While supported, it's less common for legacy system SSO or enterprise use cases compared to other options, making it a lower-priority choice here.
B . Biometrics:
Biometrics (e.g., fingerprint, facial recognition) isn't natively supported by Appian for platform authentication or integration. Appian relies on standard enterprise methods (e.g., username/password, SSO), and biometric authentication would require external identity providers or custom clients, not Appian itself. Documentation confirms no direct biometric support, ruling this out as an Appian-supported method.
C . SAML:
Security Assertion Markup Language (SAML) is fully supported by Appian for user authentication via Single Sign-On (SSO). Appian integrates with SAML 2.0 identity providers (e.g., Okta, PingFederate), allowing users to log in using credentials from legacy systems that support SAML-based SSO. This is a key enterprise method, widely used for integrating with existing identity management systems, and explicitly listed in Appian's security configuration options-making it a top choice.
D . CAC:
Common Access Card (CAC) authentication, often used in government contexts with smart cards, isn't natively supported by Appian as a standalone method. While Appian can integrate with CAC via SAML or PKI (Public Key Infrastructure) through an identity provider, it's not a direct Appian authentication option. Documentation mentions smart card support indirectly via SSO configurations, but CAC itself isn't explicitly listed, making it less definitive than other methods.
E . OAuth:
OAuth (specifically OAuth 2.0) is supported by Appian for both outbound integrations (e.g., Authorization Code Grant, Client Credentials) and inbound API authentication (e.g., securing Appian Web APIs). For legacy system integration, Appian can use OAuth to authenticate with APIs (e.g., Google, Salesforce) or allow legacy systems to call Appian services securely. Appian's Connected System framework includes OAuth configuration, making it a versatile, standards-based method highly relevant to the client's needs.
F . Active Directory:
Active Directory (AD) integration via LDAP (Lightweight Directory Access Protocol) is supported for user authentication in Appian. It allows synchronization of users and groups from AD, enabling SSO or direct login with AD credentials. For legacy systems using AD as an identity store, this is a seamless integration method. Appian's documentation confirms LDAP/AD as a core authentication option, widely adopted in enterprise environments-making it a strong fit.
Conclusion: The three supported authentication methods are C (SAML), E (OAuth), and F (Active Directory). These align with Appian's enterprise-grade capabilities for legacy system integration: SAML for SSO, OAuth for API security, and AD for user management. API Keys (A) are supported but less prominent for user authentication, CAC (D) is indirect, and Biometrics (B) isn't supported natively. This selection reassures the client of Appian's flexibility with common legacy authentication standards.
Appian Documentation: "Authentication for Connected Systems" (OAuth, API Keys).
Appian Documentation: "Configuring Authentication" (SAML, LDAP/Active Directory).
Appian Lead Developer Certification: Integration Module (Authentication Methods).
NEW QUESTION # 28
Your Appian project just went live with the following environment setup: DEV > TEST (SIT/UAT) > PROD. Your client is considering adding a support team to manage production defects and minor enhancements, while the original development team focuses on Phase 2. Your client is asking you for a new environment strategy that will have the least impact on Phase 2 development work. Which option involves the lowest additional server cost and the least code retrofit effort?
- A. Phase 2 development work stream: DEV > TEST (SIT) > STAGE (UAT) > PROD
- B. Phase 2 development work stream: DEV > TEST (SIT/UAT) > PROD
- C. Phase 2 development work stream: DEV > TEST (SIT) > STAGE (UAT) > PROD
- D. Phase 2 development work stream: DEV > TEST (SIT/UAT) > PROD
Answer: D
Explanation:
Comprehensive and Detailed In-Depth Explanation:
The goal is to design an environment strategy that minimizes additional server costs and code retrofit effort while allowing the support team to manage production defects and minor enhancements without disrupting the Phase 2 development team. The current setup (DEV > TEST (SIT/UAT) > PROD) uses a single development and testing pipeline, and the client wants to segregate support activities from Phase 2 development. Appian's Environment Management Best Practices emphasize scalability, cost efficiency, and minimal refactoring when adjusting environments.
Option C (Phase 2 development work stream: DEV > TEST (SIT/UAT) > PROD; Production support work stream: DEV > TEST2 (SIT/UAT) > PROD):
This option is the most cost-effective and requires the least code retrofit effort. It leverages the existing DEV environment for both teams but introduces a separate TEST2 environment for the support team's SIT/UAT activities. Since DEV is already shared, no new development server is needed, minimizing server costs. The existing code in DEV and TEST can be reused for TEST2 by exporting and importing packages, with minimal adjustments (e.g., updating environment-specific configurations). The Phase 2 team continues using the original TEST environment, avoiding disruption. Appian supports multiple test environments branching from a single DEV, and the PROD environment remains shared, aligning with the client's goal of low impact on Phase 2. The support team can handle defects and enhancements in TEST2 without interfering with development workflows.
Option A (Phase 2 development work stream: DEV > TEST (SIT) > STAGE (UAT) > PROD; Production support work stream: DEV > TEST2 (SIT/UAT) > PROD):
This introduces a STAGE environment for UAT in the Phase 2 stream, adding complexity and potentially requiring code updates to accommodate the new environment (e.g., adjusting deployment scripts). It also requires a new TEST2 server, increasing costs compared to Option C, where TEST2 reuses existing infrastructure.
Option B (Phase 2 development work stream: DEV > TEST (SIT) > STAGE (UAT) > PROD; Production support work stream: DEV2 > STAGE (SIT/UAT) > PROD):
This option adds both a DEV2 server for the support team and a STAGE environment, significantly increasing server costs. It also requires refactoring code to support two development environments (DEV and DEV2), including duplicating or synchronizing objects, which is more effort than reusing a single DEV.
Option D (Phase 2 development work stream: DEV > TEST (SIT/UAT) > PROD; Production support work stream: DEV2 > TEST (SIT/UAT) > PROD):
This introduces a DEV2 server for the support team, adding server costs. Sharing the TEST environment between teams could lead to conflicts (e.g., overwriting test data), potentially disrupting Phase 2 development. Code retrofit effort is higher due to managing two DEV environments and ensuring TEST compatibility.
Cost and Retrofit Analysis:
Server Cost: Option C avoids new DEV or STAGE servers, using only an additional TEST2, which can often be provisioned on existing hardware or cloud resources with minimal cost. Options A, B, and D require additional servers (TEST2, DEV2, or STAGE), increasing expenses.
Code Retrofit: Option C minimizes changes by reusing DEV and PROD, with TEST2 as a simple extension. Options A and B require updates for STAGE, and B and D involve managing multiple DEV environments, necessitating more significant refactoring.
Appian's recommendation for environment strategies in such scenarios is to maximize reuse of existing infrastructure and avoid unnecessary environment proliferation, making Option C the optimal choice.
NEW QUESTION # 29
You need to export data using an out-of-the-box Appian smart service. Which two formats are available (or data generation?
- A. JSDN
- B. XML
- C. Excel
- D. CSV
Answer: C,D
Explanation:
The two formats that are available for data generation using an out-of-the-box Appian smart service are:
A . CSV. This is a comma-separated values format that can be used to export data in a tabular form, such as records, reports, or grids. CSV files can be easily opened and manipulated by spreadsheet applications such as Excel or Google Sheets.
C . Excel. This is a format that can be used to export data in a spreadsheet form, with multiple worksheets, formatting, formulas, charts, and other features. Excel files can be opened by Excel or other compatible applications.
The other options are incorrect for the following reasons:
B . XML. This is a format that can be used to export data in a hierarchical form, using tags and attributes to define the structure and content of the data. XML files can be opened by text editors or XML parsers, but they are not supported by the out-of-the-box Appian smart service for data generation.
D . JSON. This is a format that can be used to export data in a structured form, using objects and arrays to represent the data. JSON files can be opened by text editors or JSON parsers, but they are not supported by the out-of-the-box Appian smart service for data generation. Verified Appian Documentation, section "Write to Data Store Entity" and "Write to Multiple Data Store Entities".
NEW QUESTION # 30
While working on an application, you have identified oddities and breaks in some of your components. How can you guarantee that this mistake does not happen again in the future?
- A. Design and communicate a best practice that dictates designers only work within the confines of their own application.
- B. Ensure that the application administrator group only has designers from that application's team.
- C. Create a best practice that enforces a peer review of the deletion of any components within the application.
- D. Provide Appian developers with the "Designer" permissions role within Appian. Ensure that they have only basic user rights and assign them the permissions to administer their application.
Answer: C
Explanation:
Comprehensive and Detailed In-Depth Explanation:
As an Appian Lead Developer, preventing recurring "oddities and breaks" in application components requires addressing root causes-likely tied to human error, lack of oversight, or uncontrolled changes-while leveraging Appian's governance and collaboration features. The question implies a past mistake (e.g., accidental deletions or modifications) and seeks a proactive, sustainable solution. Let's evaluate each option based on Appian's official documentation and best practices:
A . Design and communicate a best practice that dictates designers only work within the confines of their own application:
This suggests restricting designers to their assigned applications via a policy. While Appian supports application-level security (e.g., Designer role scoped to specific applications), this approach relies on voluntary compliance rather than enforcement. It doesn't directly address "oddities and breaks"-e.g., a designer could still mistakenly alter components within their own application. Appian's documentation emphasizes technical controls and process rigor over broad guidelines, making this insufficient as a guarantee.
B . Ensure that the application administrator group only has designers from that application's team:
This involves configuring security so only team-specific designers have Administrator rights to the application (via Appian's Security settings). While this limits external interference, it doesn't prevent internal mistakes (e.g., a team designer deleting a critical component). Appian's security model already restricts access by default, and the issue isn't about unauthorized access but rather component integrity. This step is a hygiene factor, not a direct solution to the problem, and fails to "guarantee" prevention.
C . Create a best practice that enforces a peer review of the deletion of any components within the application:
This is the best choice. A peer review process for deletions (e.g., process models, interfaces, or records) introduces a checkpoint to catch errors before they impact the application. In Appian, deletions are permanent and can cascade (e.g., breaking dependencies), aligning with the "oddities and breaks" described. While Appian doesn't natively enforce peer reviews, this can be implemented via team workflows-e.g., using Appian's collaboration tools (like Comments or Tasks) or integrating with version control practices during deployment. Appian Lead Developer training emphasizes change management and peer validation to maintain application stability, making this a robust, preventive measure that directly addresses the root cause.
D . Provide Appian developers with the "Designer" permissions role within Appian. Ensure that they have only basic user rights and assign them the permissions to administer their application:
This option is confusingly worded but seems to suggest granting Designer system role permissions (a high-level privilege) while limiting developers to Viewer rights system-wide, with Administrator rights only for their application. In Appian, the "Designer" system role grants broad platform access (e.g., creating applications), which contradicts "basic user rights" (Viewer role). Regardless, adjusting permissions doesn't prevent mistakes-it only controls who can make them. The issue isn't about access but about error prevention, so this option misses the mark and is impractical due to its contradictory setup.
Conclusion: Creating a best practice that enforces a peer review of the deletion of any components (C) is the strongest solution. It directly mitigates the risk of "oddities and breaks" by adding oversight to destructive actions, leveraging team collaboration, and aligning with Appian's recommended governance practices. Implementation could involve documenting the process, training the team, and using Appian's monitoring tools (e.g., Application Properties history) to track changes-ensuring mistakes are caught before deployment. This provides the closest guarantee to preventing recurrence.
Appian Documentation: "Application Security and Governance" (Change Management Best Practices).
Appian Lead Developer Certification: Application Design Module (Preventing Errors through Process).
Appian Best Practices: "Team Collaboration in Appian Development" (Peer Review Recommendations).
NEW QUESTION # 31
You are reviewing the Engine Performance Logs in Production for a single application that has been live for six months. This application experiences concurrent user activity and has a fairly sustained load during business hours. The client has reported performance issues with the application during business hours.During your investigation, you notice a high Work Queue - Java Work Queue Size value in the logs. You also notice unattended process activities, including timer events and sending notification emails, are taking far longer to execute than normal.The client increased the number of CPU cores prior to the application going live.What is the next recommendation?
- A. Optimize slow-performing user interfaces.
- B. Add more engine replicas.
- C. Add more application servers.
- D. Add execution and analytics shards
Answer: B
NEW QUESTION # 32
For each requirement, match the most appropriate approach to creating or utilizing plug-ins Each approach will be used once.
Note: To change your responses, you may deselect your response by clicking the blank space at the top of the selection list.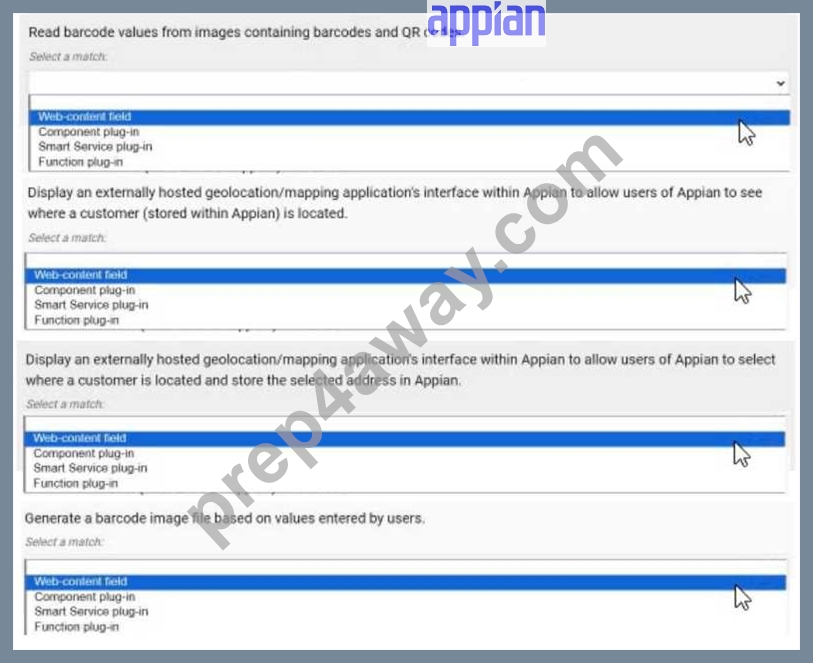
Answer:
Explanation: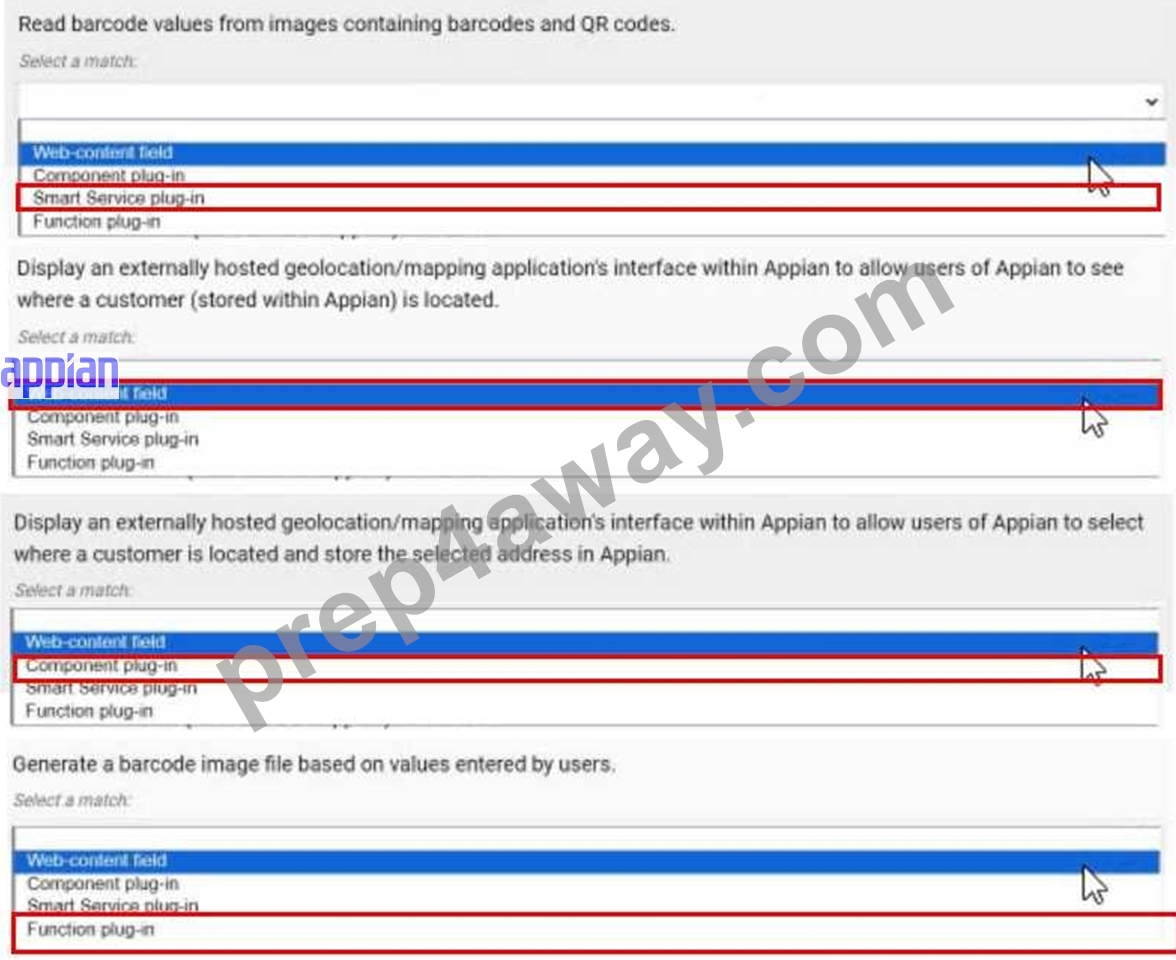
NEW QUESTION # 33
You are asked to design a case management system for a client. In addition to storing some basic metadata about a case, one of the client's requirements is the ability for users to update a case. The client would like any user in their organization of 500 people to be able to make these updates. The users are all based in the company's headquarters, and there will be frequent cases where users are attempting to edit the same case. The client wants to ensure no information is lost when these edits occur and does not want the solution to burden their process administrators with any additional effort. Which data locking approach should you recommend?
- A. Allow edits without locking the case CDI.
- B. Design a process report and query to determine who opened the edit form first.
- C. Use the database to implement low-level pessimistic locking.
- D. Add an @Version annotation to the case CDT to manage the locking.
Answer: D
Explanation:
Comprehensive and Detailed In-Depth Explanation:
The requirement involves a case management system where 500 users may simultaneously edit the same case, with a need to prevent data loss and minimize administrative overhead. Appian's data management and concurrency control strategies are critical here, especially when integrating with an underlying database.
Option C (Add an @Version annotation to the case CDT to manage the locking):
This is the recommended approach. In Appian, the @Version annotation on a Custom Data Type (CDT) enables optimistic locking, a lightweight concurrency control mechanism. When a user updates a case, Appian checks the version number of the CDT instance. If another user has modified it in the meantime, the update fails, prompting the user to refresh and reapply changes. This prevents data loss without requiring manual intervention by process administrators. Appian's Data Design Guide recommends @Version for scenarios with high concurrency (e.g., 500 users) and frequent edits, as it leverages the database's native versioning (e.g., in MySQL or PostgreSQL) and integrates seamlessly with Appian's process models. This aligns with the client's no-burden requirement.
Option A (Allow edits without locking the case CDI):
This is risky. Without locking, simultaneous edits could overwrite each other, leading to data loss-a direct violation of the client's requirement. Appian does not recommend this for collaborative environments.
Option B (Use the database to implement low-level pessimistic locking):
Pessimistic locking (e.g., using SELECT ... FOR UPDATE in MySQL) locks the record during the edit process, preventing other users from modifying it until the lock is released. While effective, it can lead to deadlocks or performance bottlenecks with 500 users, especially if edits are frequent. Additionally, managing this at the database level requires custom SQL and increases administrative effort (e.g., monitoring locks), which the client wants to avoid. Appian prefers higher-level solutions like @Version over low-level database locking.
Option D (Design a process report and query to determine who opened the edit form first):
This is impractical and inefficient. Building a custom report and query to track form opens adds complexity and administrative overhead. It doesn't inherently prevent data loss and relies on manual resolution, conflicting with the client's requirements.
The @Version annotation provides a robust, Appian-native solution that balances concurrency, data integrity, and ease of maintenance, making it the best fit.
NEW QUESTION # 34
You are just starting with a new team that has been working together on an application for months. They ask you to review some of their views that have been degrading in performance. The views are highly complex with hundreds of lines of SQL. What is the first step in troubleshooting the degradation?
- A. Browse through the tables, note any tables that contain a large volume of null values, and work with your team to plan for table restructure.
- B. Go through the entire database structure to obtain an overview, ensure you understand the business needs, and then normalize the tables to optimize performance.
- C. Go through all of the tables one by one to identify which of the grouped by, ordered by, or joined keys are currently indexed.
- D. Run an explain statement on the views, identify critical areas of improvement that can be remediated without business knowledge.
Answer: D
Explanation:
Comprehensive and Detailed In-Depth Explanation:
Troubleshooting performance degradation in complex SQL views within an Appian application requires a systematic approach. The views, described as having hundreds of lines of SQL, suggest potential issues with query execution, indexing, or join efficiency. As a new team member, the first step should focus on quickly identifying the root cause without overhauling the system prematurely. Appian's Performance Troubleshooting Guide and database optimization best practices provide the framework for this process.
Option B (Run an explain statement on the views, identify critical areas of improvement that can be remediated without business knowledge):
This is the recommended first step. Running an EXPLAIN statement (or equivalent, such as EXPLAIN PLAN in some databases) analyzes the query execution plan, revealing details like full table scans, missing indices, or inefficient joins. This technical analysis can identify immediate optimization opportunities (e.g., adding indices or rewriting subqueries) without requiring business input, allowing you to address low-hanging fruit quickly. Appian encourages using database tools to diagnose performance issues before involving stakeholders, making this a practical starting point as you familiarize yourself with the application.
Option A (Go through the entire database structure to obtain an overview, ensure you understand the business needs, and then normalize the tables to optimize performance):
This is too broad and time-consuming as a first step. Understanding business needs and normalizing tables are valuable but require collaboration with the team and stakeholders, delaying action. It's better suited for a later phase after initial technical analysis.
Option C (Go through all of the tables one by one to identify which of the grouped by, ordered by, or joined keys are currently indexed):
Manually checking indices is useful but inefficient without first knowing which queries are problematic. The EXPLAIN statement provides targeted insights into index usage, making it a more direct initial step than a manual table-by-table review.
Option D (Browse through the tables, note any tables that contain a large volume of null values, and work with your team to plan for table restructure):
Identifying null values and planning restructures is a long-term optimization strategy, not a first step. It requires team input and may not address the immediate performance degradation, which is better tackled with query-level diagnostics.
Starting with an EXPLAIN statement allows you to gather data-driven insights, align with Appian's performance troubleshooting methodology, and proceed with informed optimizations.
NEW QUESTION # 35
Your Agile Scrum project requires you to manage two teams, with three developers per team. Both teams are to work on the same application in parallel. How should the work be divided between the teams, avoiding issues caused by cross-dependency?
- A. Group epics and stories by technical difficulty, and allocate one team the more challenging stories.
- B. Allocate stories to each team based on the cumulative years of experience of the team members.
- C. Have each team choose the stories they would like to work on based on personal preference.
- D. Group epics and stories by feature, and allocate work between each team by feature.
Answer: D
Explanation:
Comprehensive and Detailed In-Depth Explanation:
In an Agile Scrum environment with two teams working on the same application in parallel, effective work division is critical to avoid cross-dependency, which can lead to delays, conflicts, and inefficiencies. Appian's Agile Development Best Practices emphasize team autonomy and minimizing dependencies to ensure smooth progress.
Option B (Group epics and stories by feature, and allocate work between each team by feature):
This is the recommended approach. By dividing the application's functionality into distinct features (e.g., Team 1 handles customer management, Team 2 handles campaign tracking), each team can work independently on a specific domain. This reduces cross-dependency because teams are not reliant on each other's deliverables within a sprint. Appian's guidance on multi-team projects suggests feature-based partitioning as a best practice, allowing teams to own their backlog items, design, and testing without frequent coordination. For example, Team 1 can develop and test customer-related interfaces while Team 2 works on campaign processes, merging their work during integration phases.
Option A (Group epics and stories by technical difficulty, and allocate one team the more challenging stories):
This creates an imbalance, potentially overloading one team and underutilizing the other, which can lead to morale issues and uneven progress. It also doesn't address cross-dependency, as challenging stories might still require input from both teams (e.g., shared data models), increasing coordination needs.
Option C (Allocate stories to each team based on the cumulative years of experience of the team members):
Experience-based allocation ignores the project's functional structure and can result in mismatched skills for specific features. It also risks dependencies if experienced team members are needed across teams, complicating parallel work.
Option D (Have each team choose the stories they would like to work on based on personal preference):
This lacks structure and could lead to overlap, duplication, or neglect of critical features. It increases the risk of cross-dependency as teams might select interdependent stories without coordination, undermining parallel development.
Feature-based division aligns with Scrum principles of self-organization and minimizes dependencies, making it the most effective strategy for this scenario.
NEW QUESTION # 36
Your application contains a process model that is scheduled to run daily at a certain time, which kicks off a user input task to a specified user on the 1st time zone for morning data collection. The time zone is set to the (default) pm!timezone. In this situation, what does the pm!timezone reflect?
- A. The default time zone for the environment as specified in the Administration Console.
- B. The time zone of the server where Appian is installed.
- C. The time zone of the user who is completing the input task.
- D. The time zone of the user who most recently published the process model.
Answer: A
Explanation:
Comprehensive and Detailed In-Depth Explanation:
In Appian, the pm!timezone variable is a process variable automatically available in process models, reflecting the time zone context for scheduled or time-based operations. Understanding its behavior is critical for scheduling tasks accurately, especially in scenarios like this where a process runs daily and assigns a user input task.
Option C (The default time zone for the environment as specified in the Administration Console):
This is the correct answer. Per Appian's Process Model documentation, when a process model uses pm!timezone and no custom time zone is explicitly set, it defaults to the environment's time zone configured in the Administration Console (under System > Time Zone settings). For scheduled processes, such as one running "daily at a certain time," Appian uses this default time zone to determine when the process triggers. In this case, the task assignment occurs based on the schedule, and pm!timezone reflects the environment's setting, not the user's location.
Option A (The time zone of the server where Appian is installed): This is incorrect. While the server's time zone might influence underlying system operations, Appian abstracts this through the Administration Console's time zone setting. The pm!timezone variable aligns with the configured environment time zone, not the raw server setting.
Option B (The time zone of the user who most recently published the process model): This is irrelevant. Publishing a process model does not tie pm!timezone to the publisher's time zone. Appian's scheduling is system-driven, not user-driven in this context.
Option D (The time zone of the user who is completing the input task): This is also incorrect. While Appian can adjust task display times in the user interface to the assigned user's time zone (based on their profile settings), the pm!timezone in the process model reflects the environment's default time zone for scheduling purposes, not the assignee's.
For example, if the Administration Console is set to EST (Eastern Standard Time), the process will trigger daily at the specified time in EST, regardless of the assigned user's location. The "1st time zone" phrasing in the question appears to be a typo or miscommunication, but it doesn't change the fact that pm!timezone defaults to the environment setting.
NEW QUESTION # 37
......
Provide Valid Dumps To Help You Prepare For Appian Certified Lead Developer Exam: https://actualtests.prep4away.com/Appian-certification/braindumps.ACD-301.ete.file.html